Russian-Speech Avatar Lip-Sync from a Video Reference
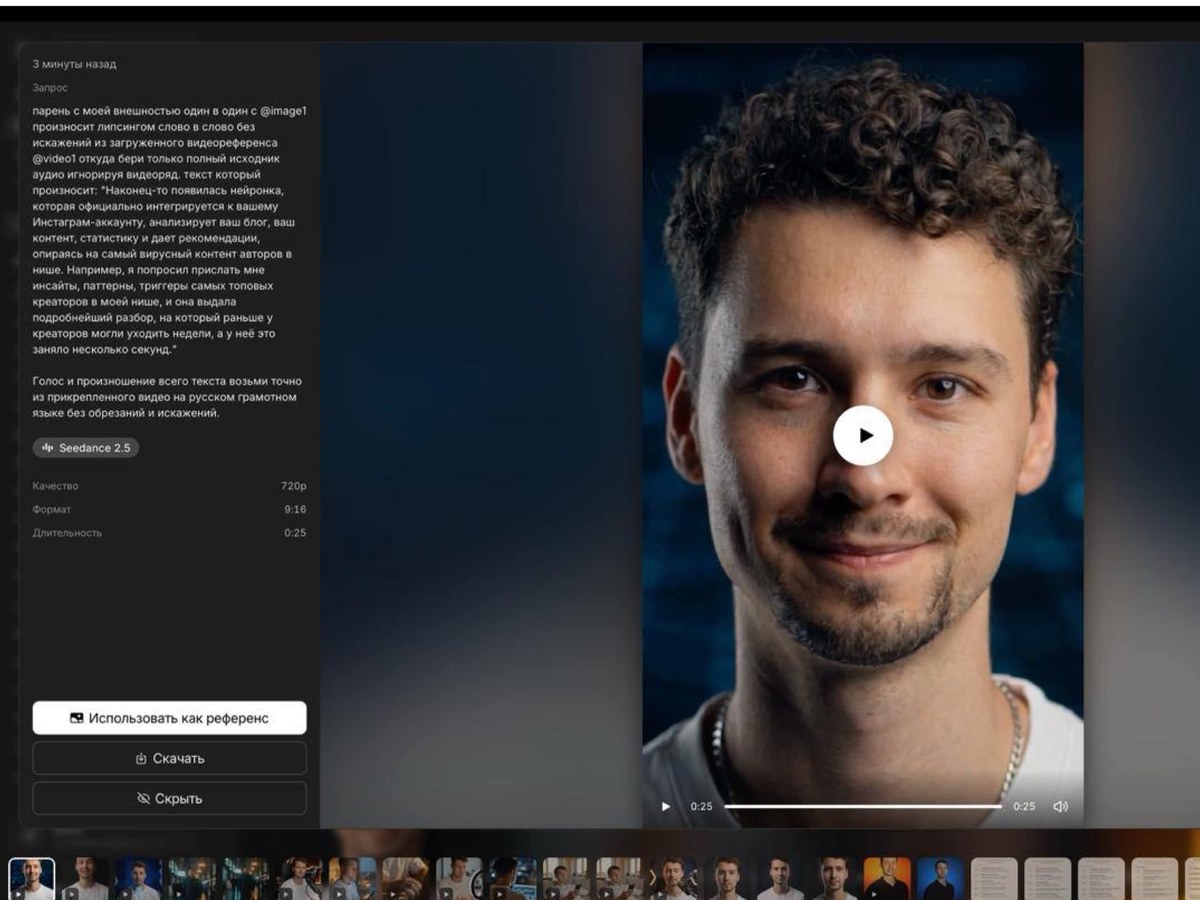
Create a male avatar matching a reference image and lip-sync supplied Russian text using the voice and complete original audio from a video reference, while ignoring that video’s visuals.
Example outputs
Prompt template
- Format
- Text Parameterized
- Inputs
- reference_image (image) · Required video_reference (video) · Required spoken_text (text) · Required
- Outputs
- LipSync_avatar_video (video)
Create a male avatar whose appearance matches ${reference-image} exactly. Have him lip-sync the following text word for word, without alterations: ${spoken-text}.

Use ${video-reference} only as the source for its complete original audio; ignore its visuals. Match the voice and pronunciation from that audio exactly. Deliver the full text in grammatically correct Russian, without cuts or distortion.
Replace the ${…} placeholders with your values
before using this prompt. See parameters
and defaults below
Parameters
Replace each placeholder with your own value, or use its default when one is provided
${reference-image}
reference-image
Required
${spoken-text}
spoken-text
Required
${video-reference}
video-reference
Required
What you'll create
The avatar’s visual identity comes from an image, while pronunciation and voice follow the complete source audio. The requested Russian text remains unaltered and uncut.
Frequently asked questions
Should the audio video’s visuals guide the avatar?
No. That reference supplies audio only; its visuals are explicitly ignored.


Comments
Tried this prompt? Share what you made, compare results, or ask a question